Uptime monitoring
Monitor availability in Maple: alert on traffic stopping and failing requests from your traces, and add HTTP checks from the OpenTelemetry Collector for endpoints and TLS certificates.
Maple monitors availability from two sources. Alert rules on your traces fire when a service stops receiving requests or starts failing them. HTTP checks from the OpenTelemetry Collector cover what real traffic cannot: endpoints with little traffic, and failures that happen before a request reaches your code, such as a DNS change or an expired certificate.
Maple does not run hosted probes. The checks run in a Collector you operate.
Recommended reading first. Uptime monitoring with traces and HTTP checks is the background for this page: which failures a probe catches, which ones only traces see, and when a probe is worth adding. This page is the setup.
Prerequisites
- Traces arriving from the services you want to watch.
- At least one notification destination.
- For HTTP checks: the OpenTelemetry Collector Contrib distribution (
otelcol-contrib) on a host outside the system it checks, and a private ingest key (maple_sk_…) from Settings → Ingestion.
Alert on real traffic
- Open Alerts, click New rule and pick the Throughput drop template.
- Under Scope, select the service. The template sets Min samples to 0, so a window with no requests counts as zero and fires.
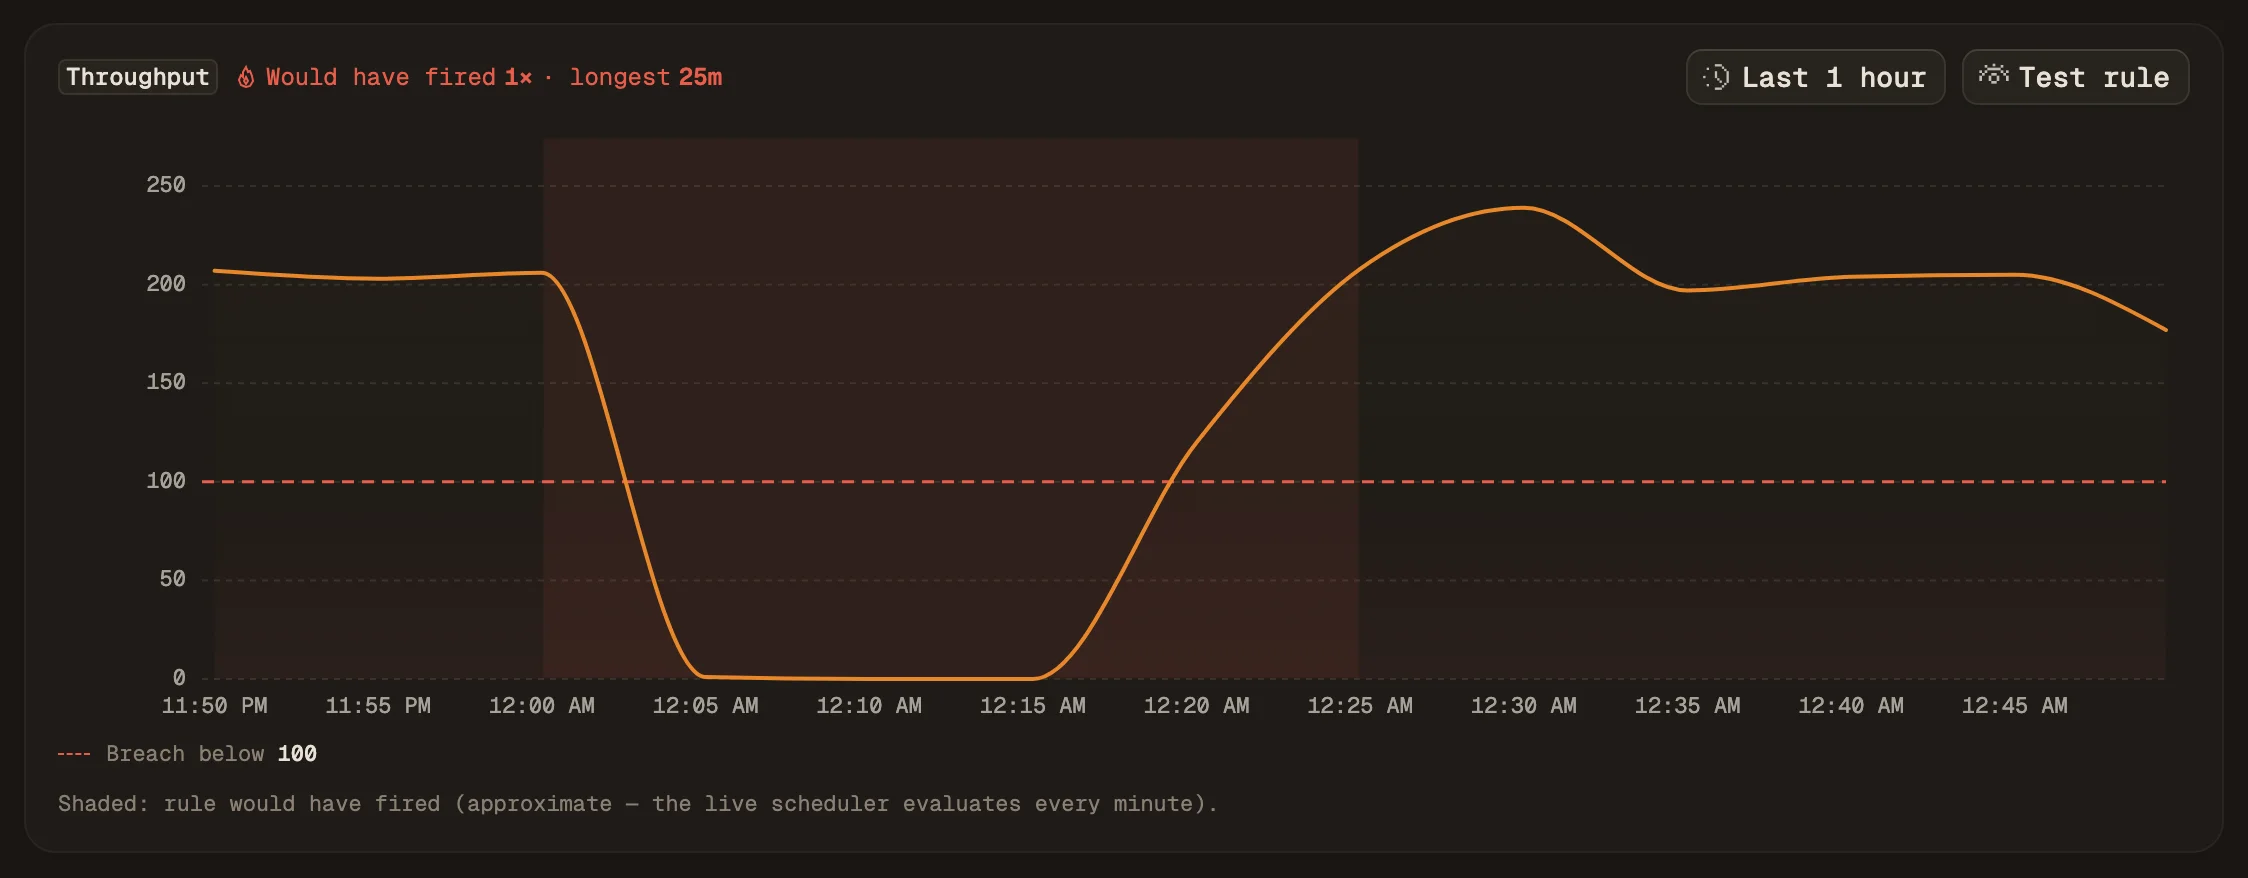
- Set Threshold below the service’s quietest five minutes on a normal day.
- Pick a range above the chart to replay the rule. The shaded periods are where it would have held an incident open.
- Attach a destination and click Create rule.
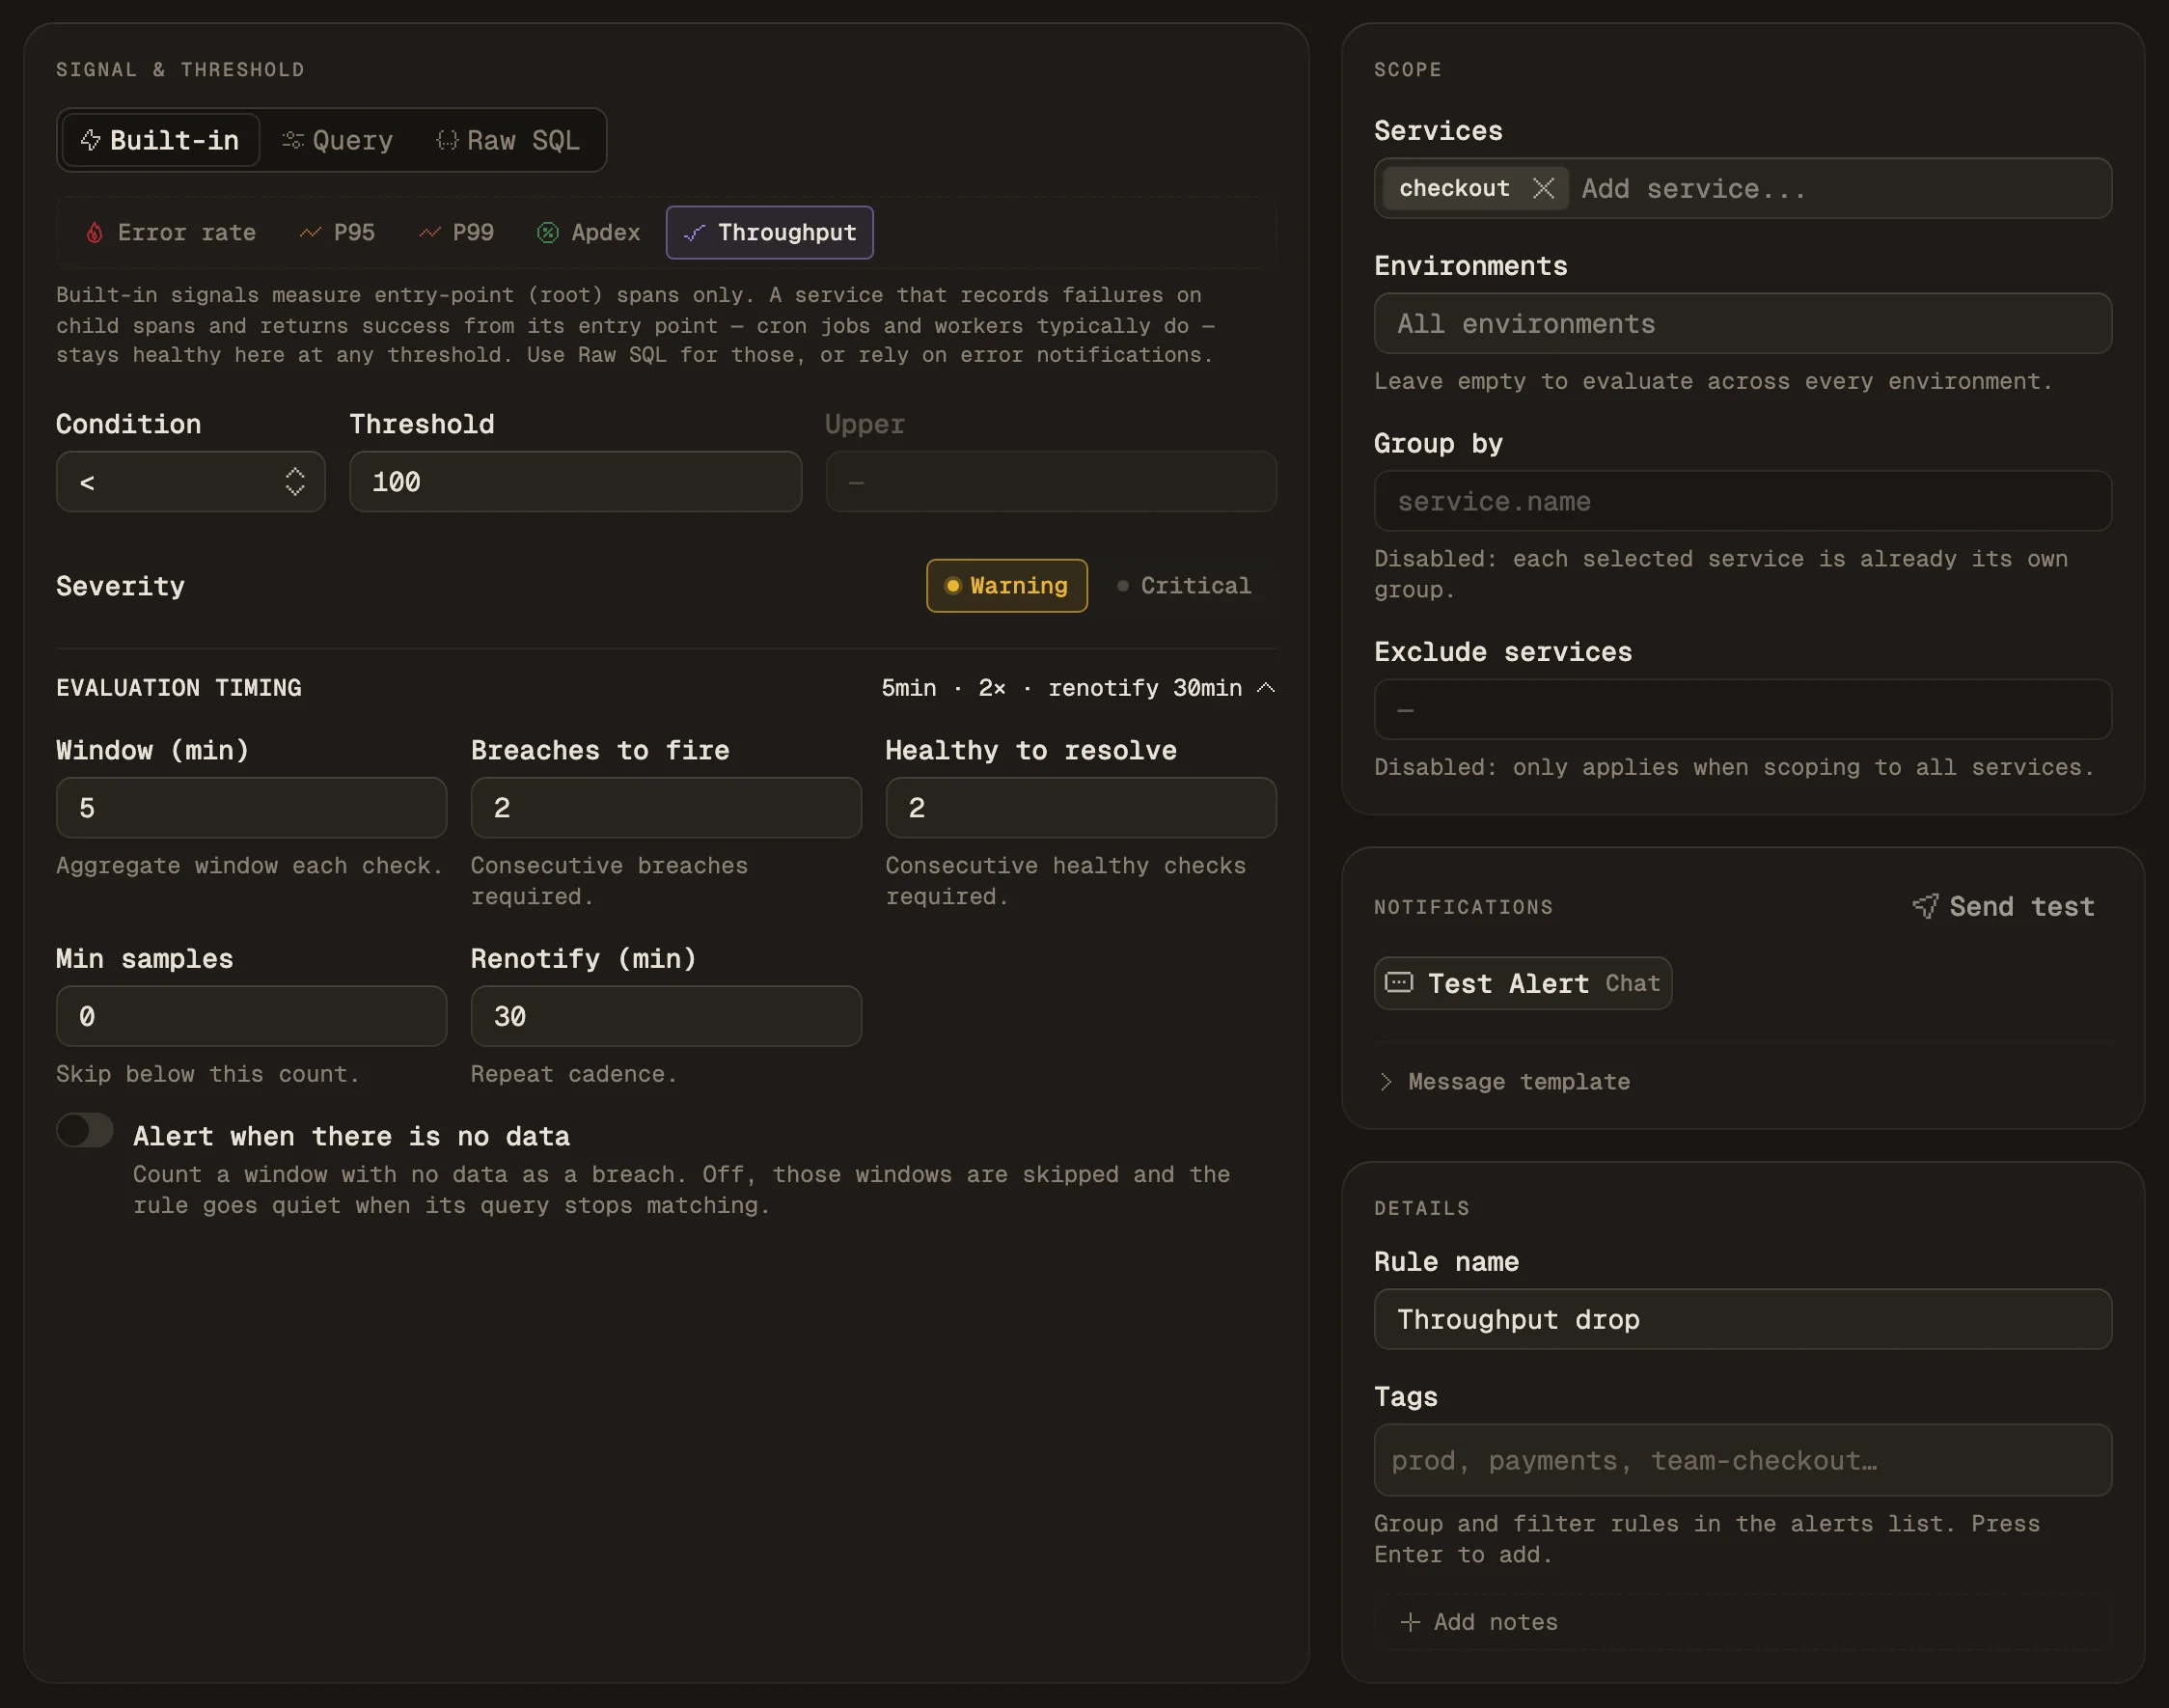
Add the High error rate template for failing requests and Low Apdex score for slow ones. Alert rules describes every field.
A throughput rule needs traffic to drop from. For a service that sits idle for hours, use an HTTP check.
Add HTTP checks
The Collector’s http_check receiver requests a list of URLs on an interval and reports each result as metrics. Save this as config.yaml:
receivers:
    http_check:
        collection_interval: 60s
        metrics:
            httpcheck.tls.cert_remaining:
                enabled: true
        targets:
            - method: GET
              endpoints:
                  - https://example.com
                  - https://api.example.com/health

processors:
    resource/uptime:
        attributes:
            - key: service.name
              value: uptime-checks
              action: upsert
    batch: {}

exporters:
    otlphttp/maple:
        endpoint: https://ingest.maple.dev
        compression: gzip
        headers:
            x-maple-ingest-key: ${env:MAPLE_INGEST_KEY}

service:
    pipelines:
        metrics/uptime:
            receivers: [http_check]
            processors: [resource/uptime, batch]
            exporters: [otlphttp/maple]
Start the Collector with your key in the environment:
MAPLE_INGEST_KEY=YOUR_INGEST_KEY otelcol-contrib --config config.yamlNotes on the config:
- Older Collector releases name the receiver
httpcheck. Use that name in both places if your release rejectshttp_check. resource/uptimesetsservice.name. The checks appear in Maple under the serviceuptime-checks.- EU organizations use
https://ingest.eu.maple.devas the endpoint. - Run the Collector outside the system it checks. On the same machine as the service, it goes down with it.
What the receiver reports
| Metric | Value |
|---|---|
httpcheck.status | One data point per status class (1xx to 5xx): 1 for the class the response matched, 0 for the rest. A failed connection reports 0 for every class. |
httpcheck.error | 1 when the request failed before a response arrived, with the reason in error.message. |
httpcheck.duration | Total request time in milliseconds. |
httpcheck.tls.cert_remaining | Seconds until the certificate expires. Off unless enabled, as in the config above. |
Every data point carries the checked address in http.url.
Alert when an endpoint stops answering
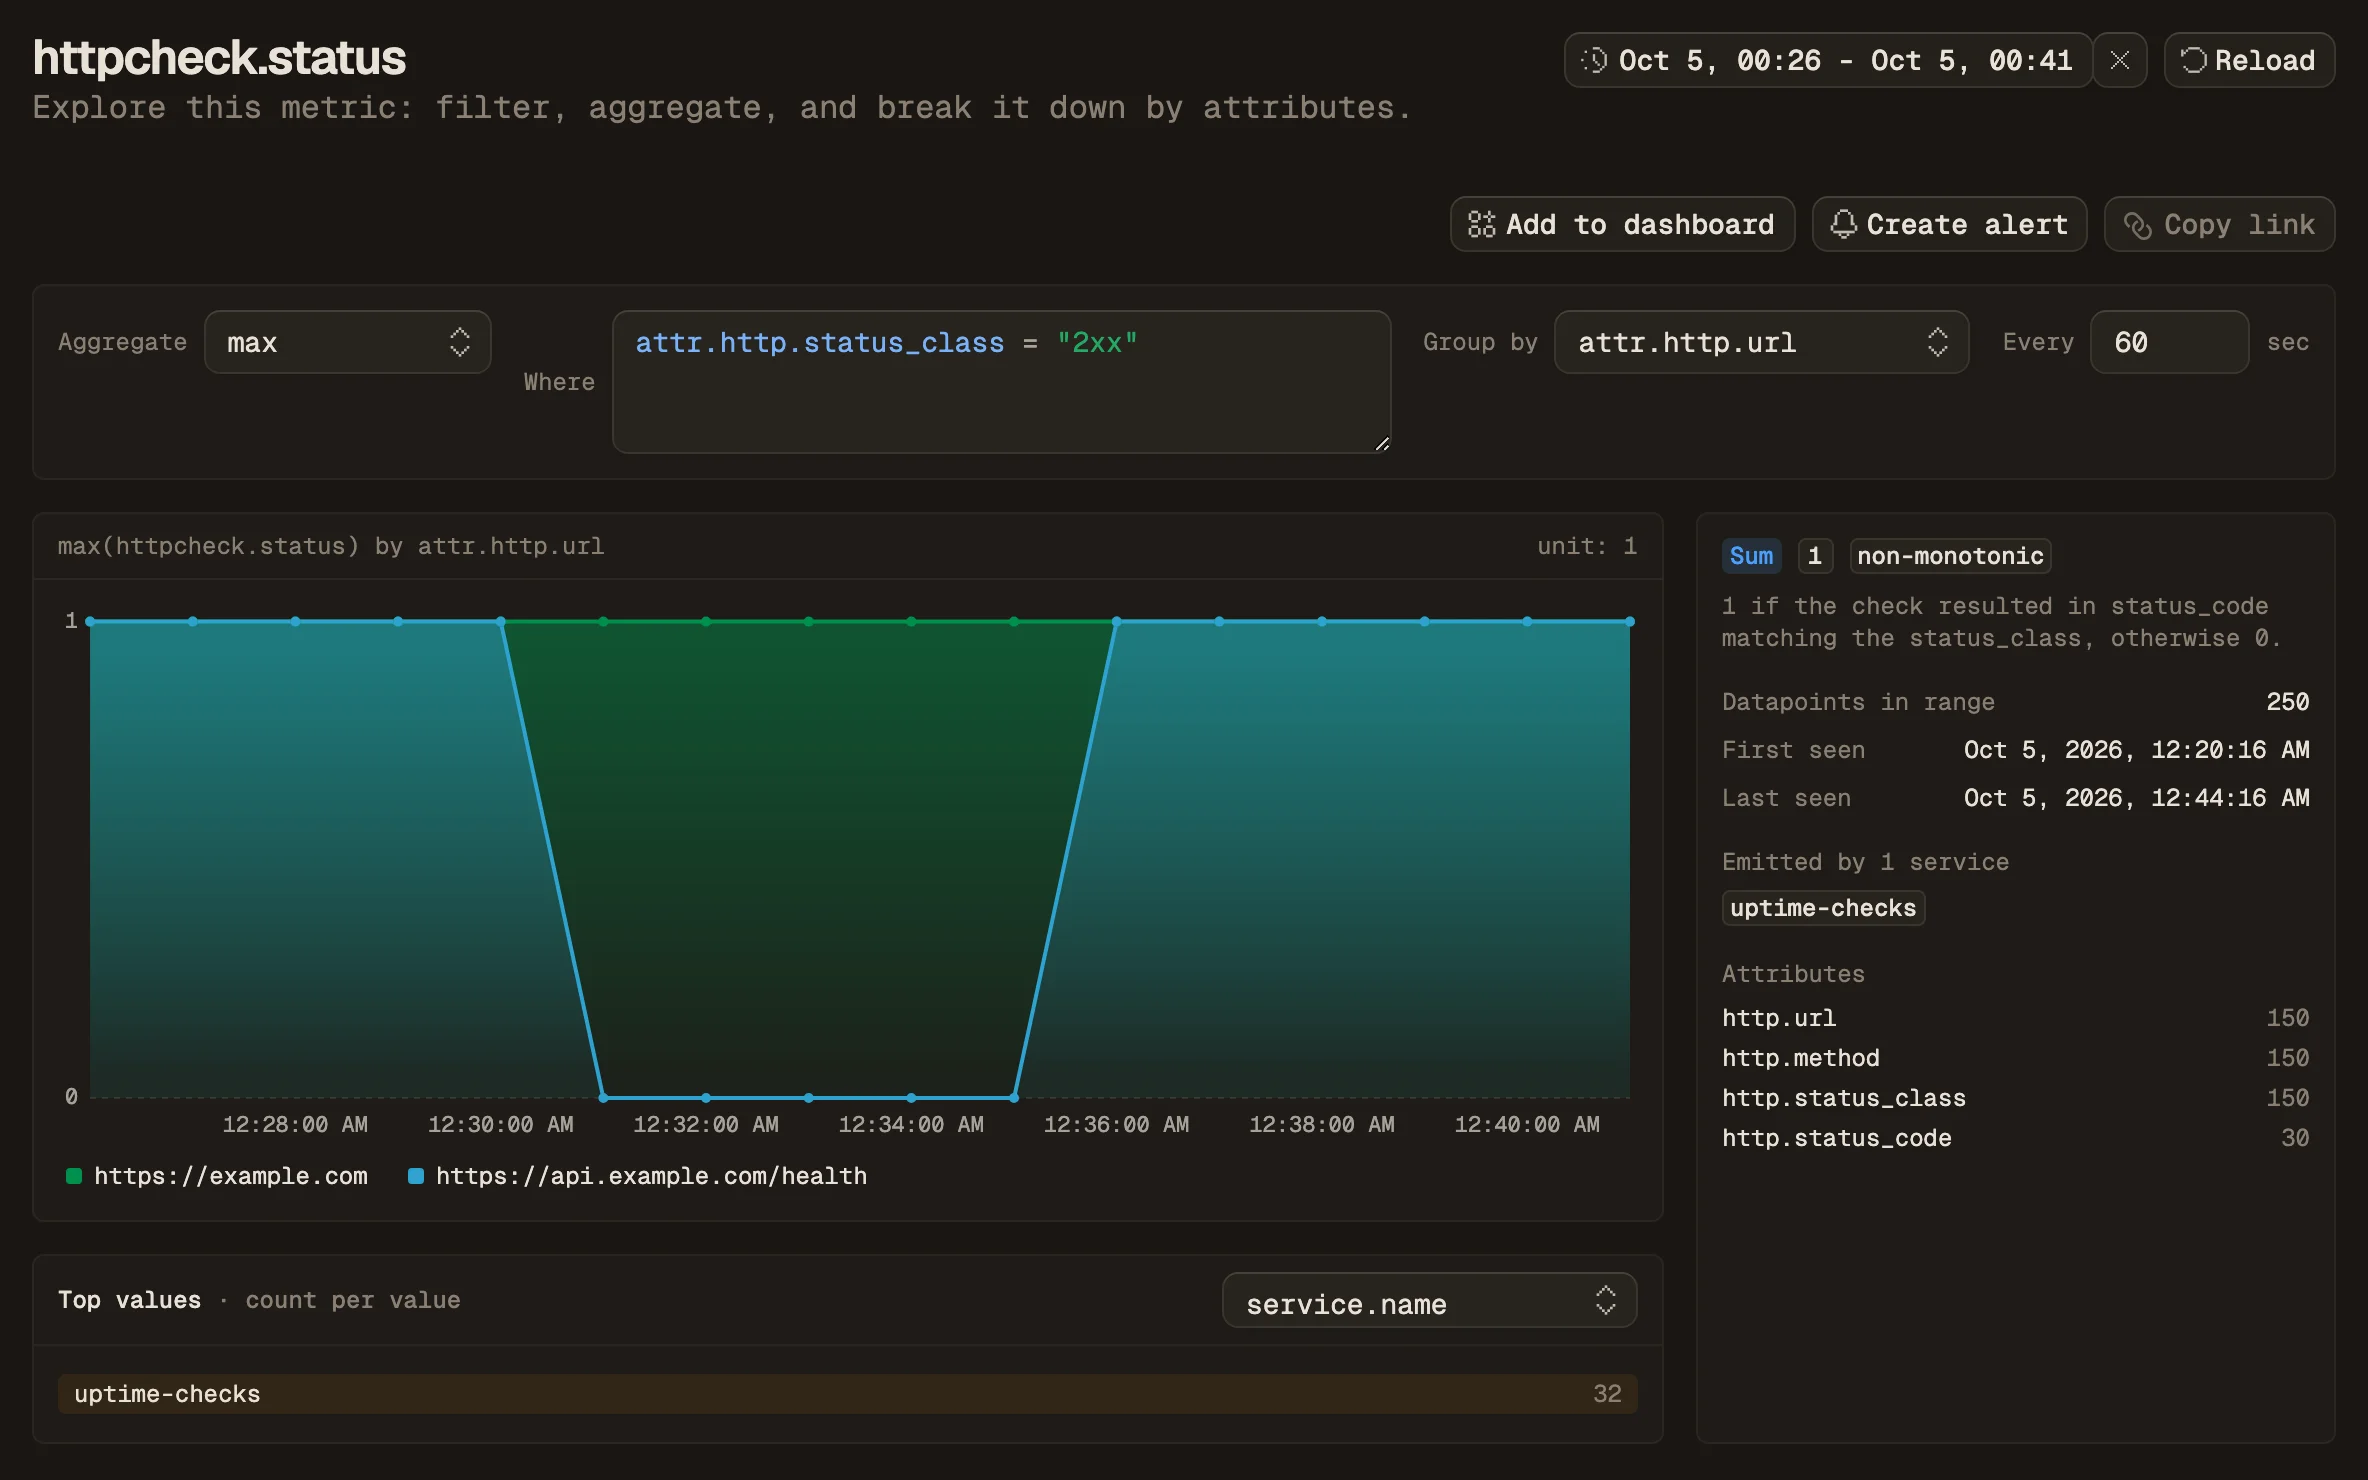
- Open Metrics and open
httpcheck.status. - Set Aggregate to
max, Where toattr.http.status_class = "2xx", and Group by toattr.http.url. Keep theattr.prefix on the filter, or it is dropped when the chart becomes a rule. - Click Create alert.
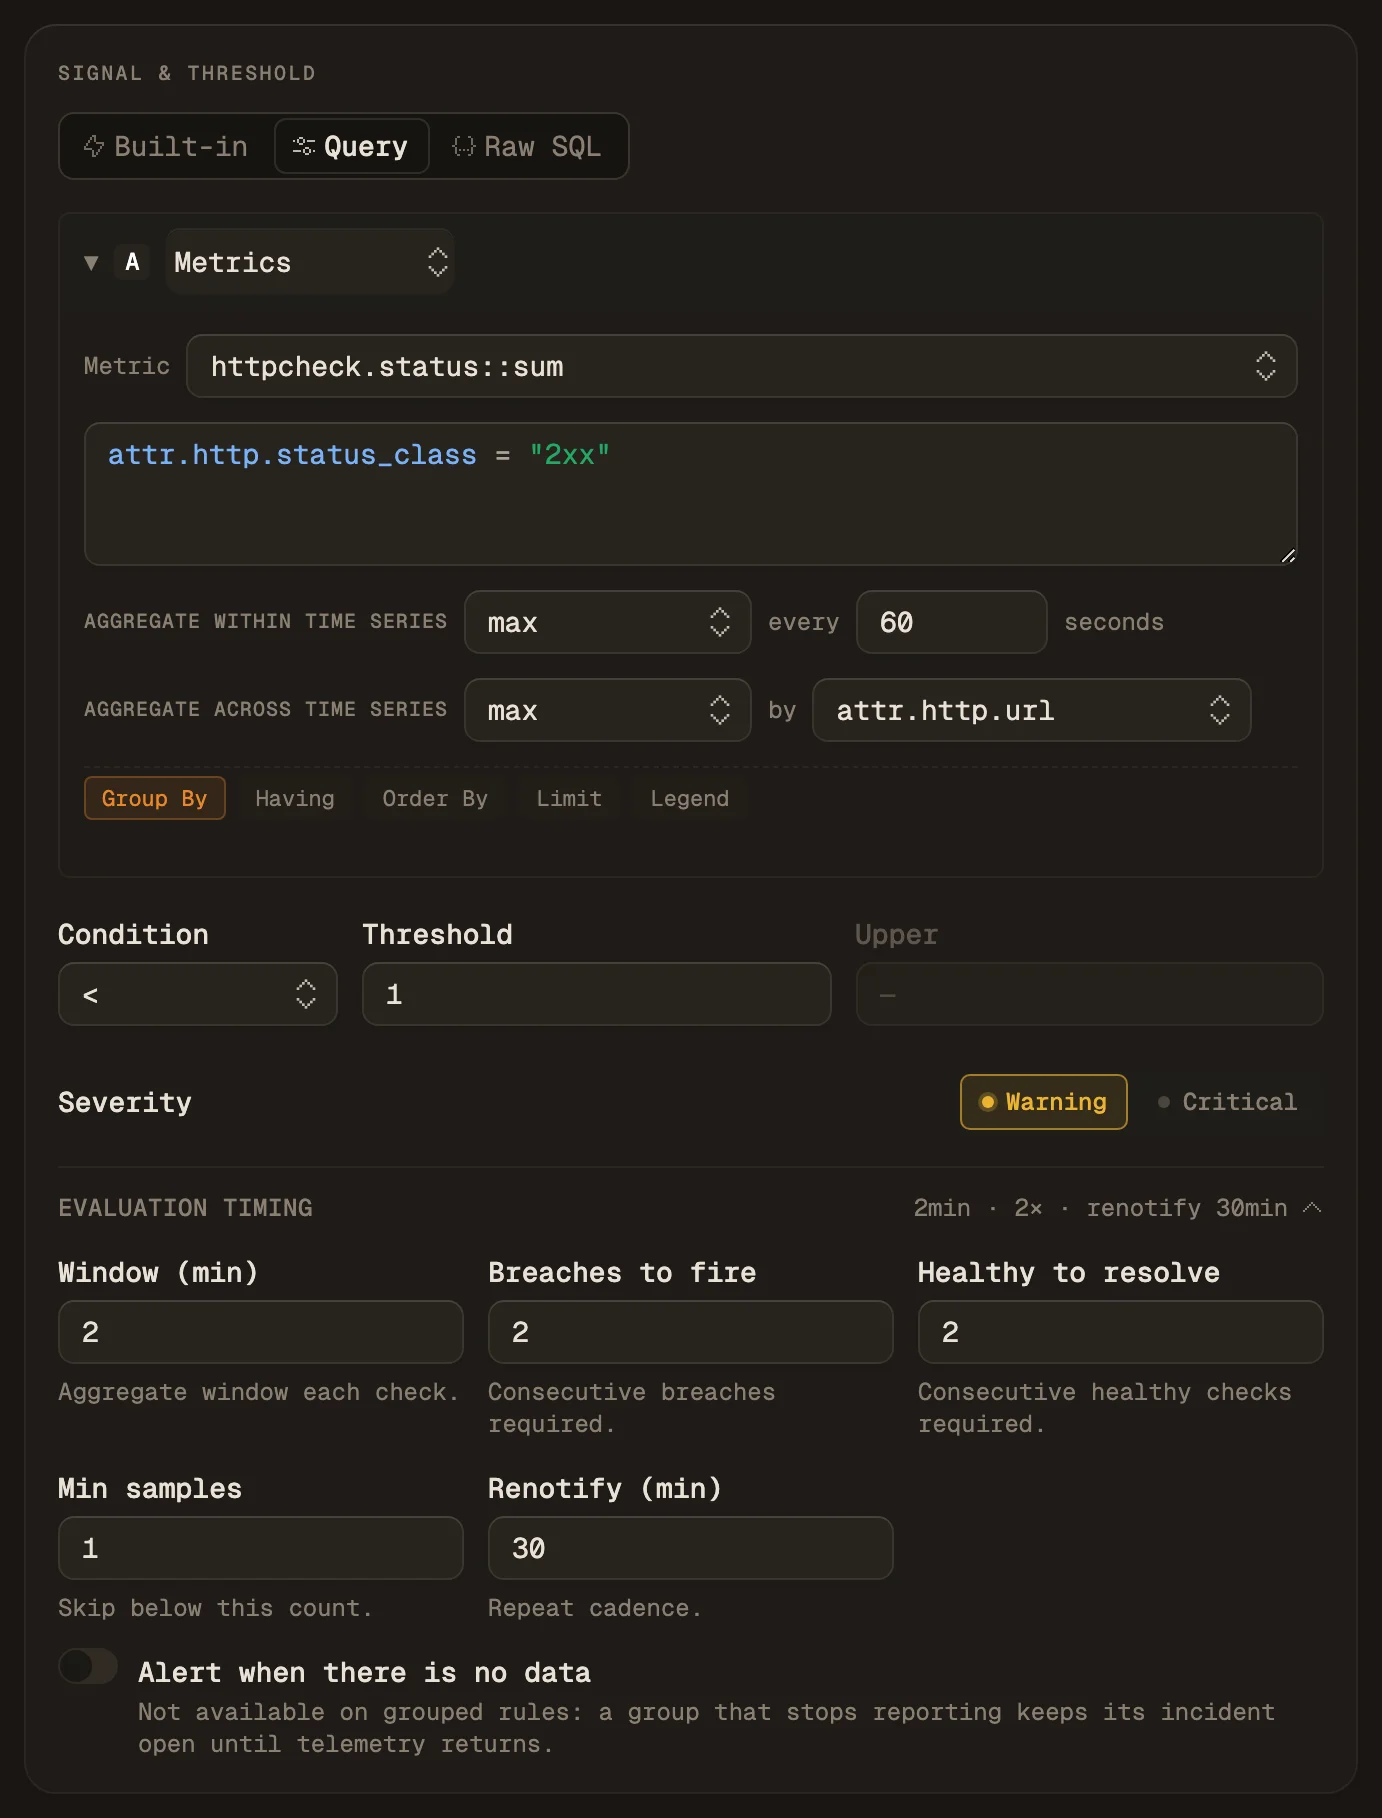
- Set Condition to
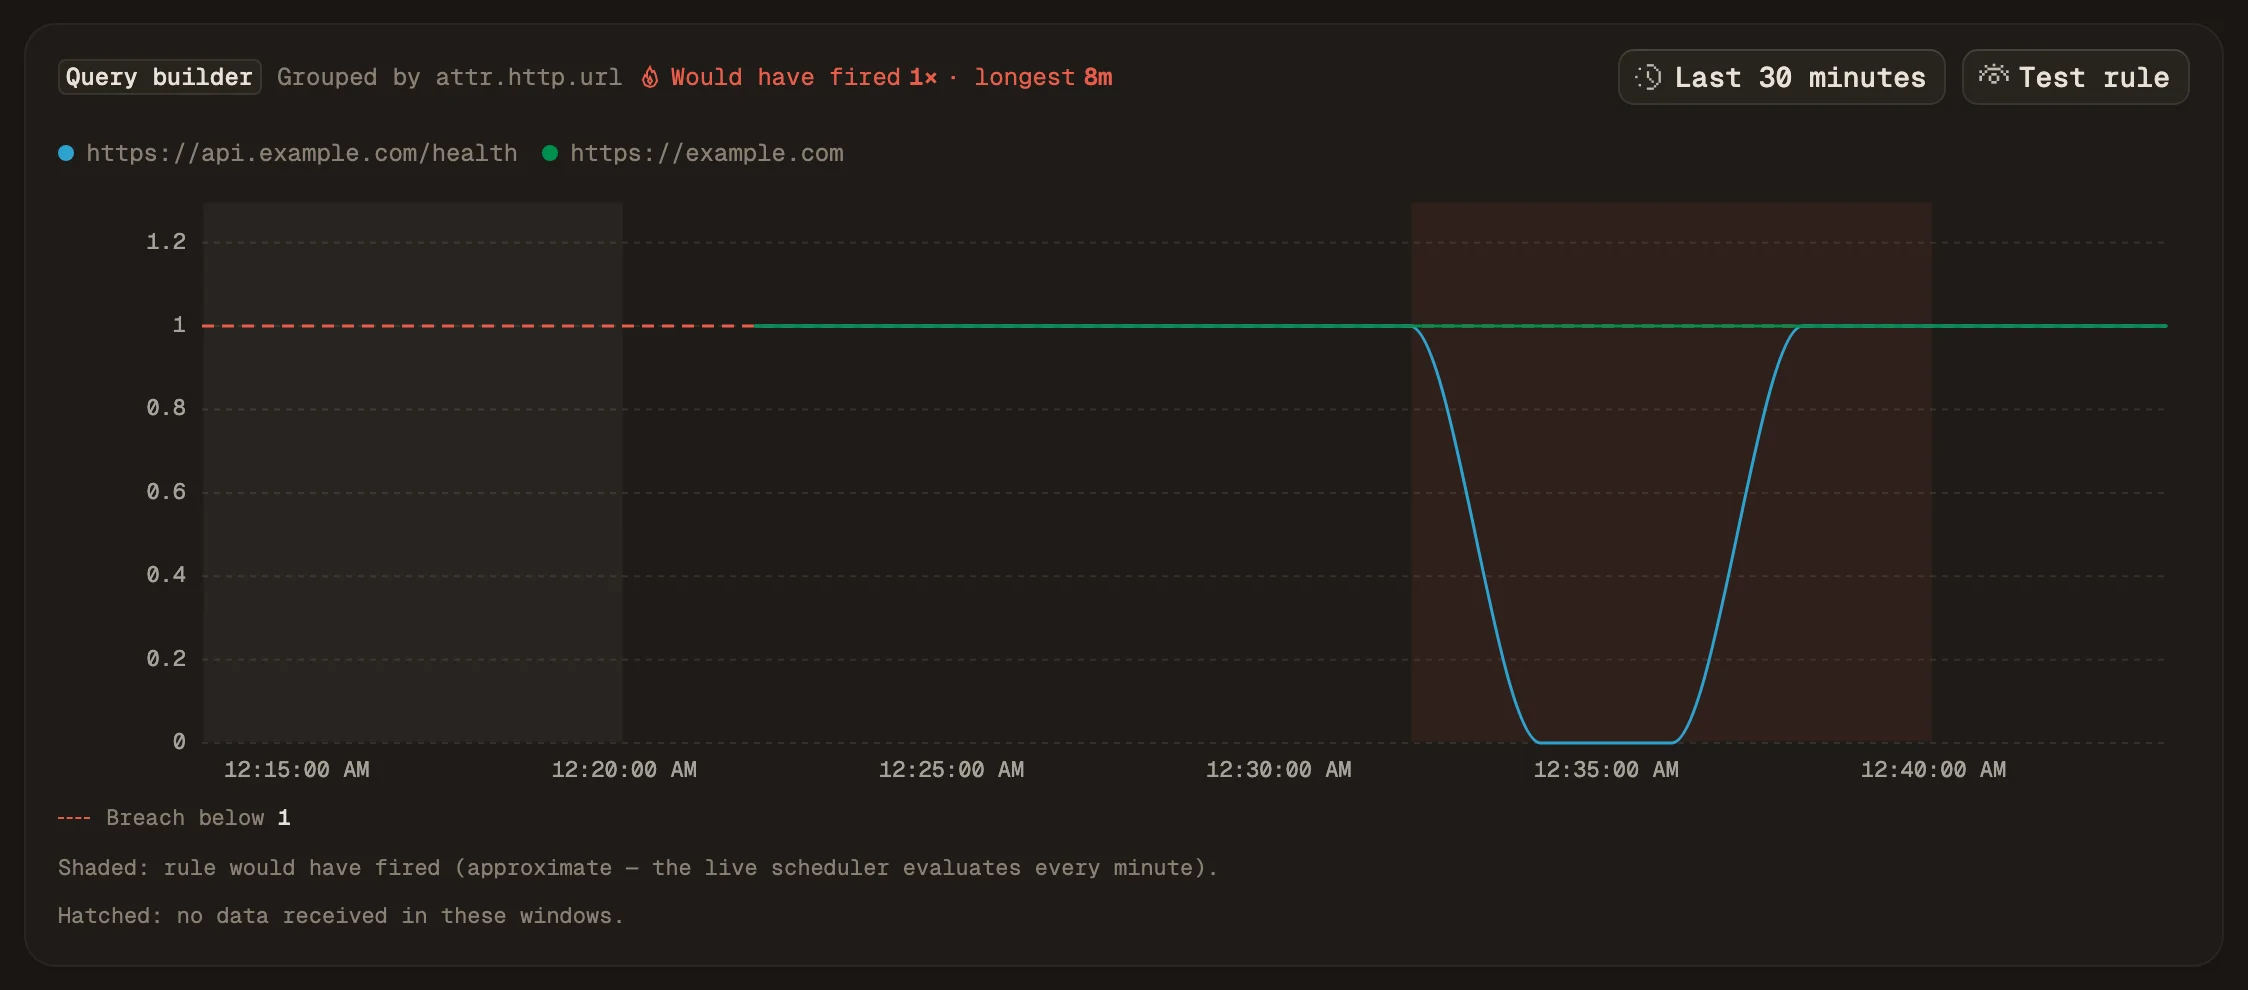
<and Threshold to1. - Open Evaluation timing. Set Window (min) to 2 and Min samples to 1. A two-minute window holds two data points per URL, so the default of 50 would skip every check.
- Leave Breaches to fire at 2.
- Attach a destination and click Create rule.
The rule reads: no check of this URL returned a 2xx in the last two minutes. It opens one incident per URL, about three minutes into an outage, and one failed check on its own does not fire it.
Alert when the checks stop arriving
A grouped rule skips a window with no data, so a stopped Collector would go unnoticed. Create a second rule on httpcheck.status with no group-by:
- Aggregate
count, Condition<, Threshold1 - Min samples 1
- Alert when there is no data switched on
Alert before a certificate expires
Create a rule on httpcheck.tls.cert_remaining:
- Aggregate
min, Group byattr.http.url - Condition
<, Threshold1209600(14 days in seconds) - Min samples 1
Verify
Open Metrics and search for httpcheck. The metrics appear after the first check, emitted by the service uptime-checks. Open httpcheck.status and group by attr.http.url to see one series per target.
Limits
- One Collector probes from one place, through one DNS resolver. It cannot show that users in another region are cut off, and a network problem next to the Collector looks the same as an outage.
- There is no status page.
For probes from several regions, a public status page, or an availability report for customers, run a dedicated uptime product next to Maple.
Troubleshooting
- No
httpcheckmetrics appear. Check the Collector’s output for exporter errors. A401means the ingest key is wrong or was rotated. - The alert form warns “Unsupported metrics filter ignored”. The filter key is missing the
attr.prefix. Useattr.http.status_class. - Every check of the rule is skipped. The window holds fewer data points than Min samples. Set it to 1.
- The rule fires on a single failed check. Aggregate is
min. Withmax, every check in the window has to fail.
Next steps
- Alert rules: every signal, field and template.
- Incidents: what happens after a rule fires.
- Metrics: chart
httpcheck.durationand the other check metrics. - Uptime monitoring with traces and HTTP checks: the reasoning behind this setup.