The path
Two hops from the symptom to the cause
payment-svc@1.4.2 shipped four hours before latency went up. The map, the trace and the logs below are all filtered to it.
- map T+0:00 · deploy payment-svc@1.4.2
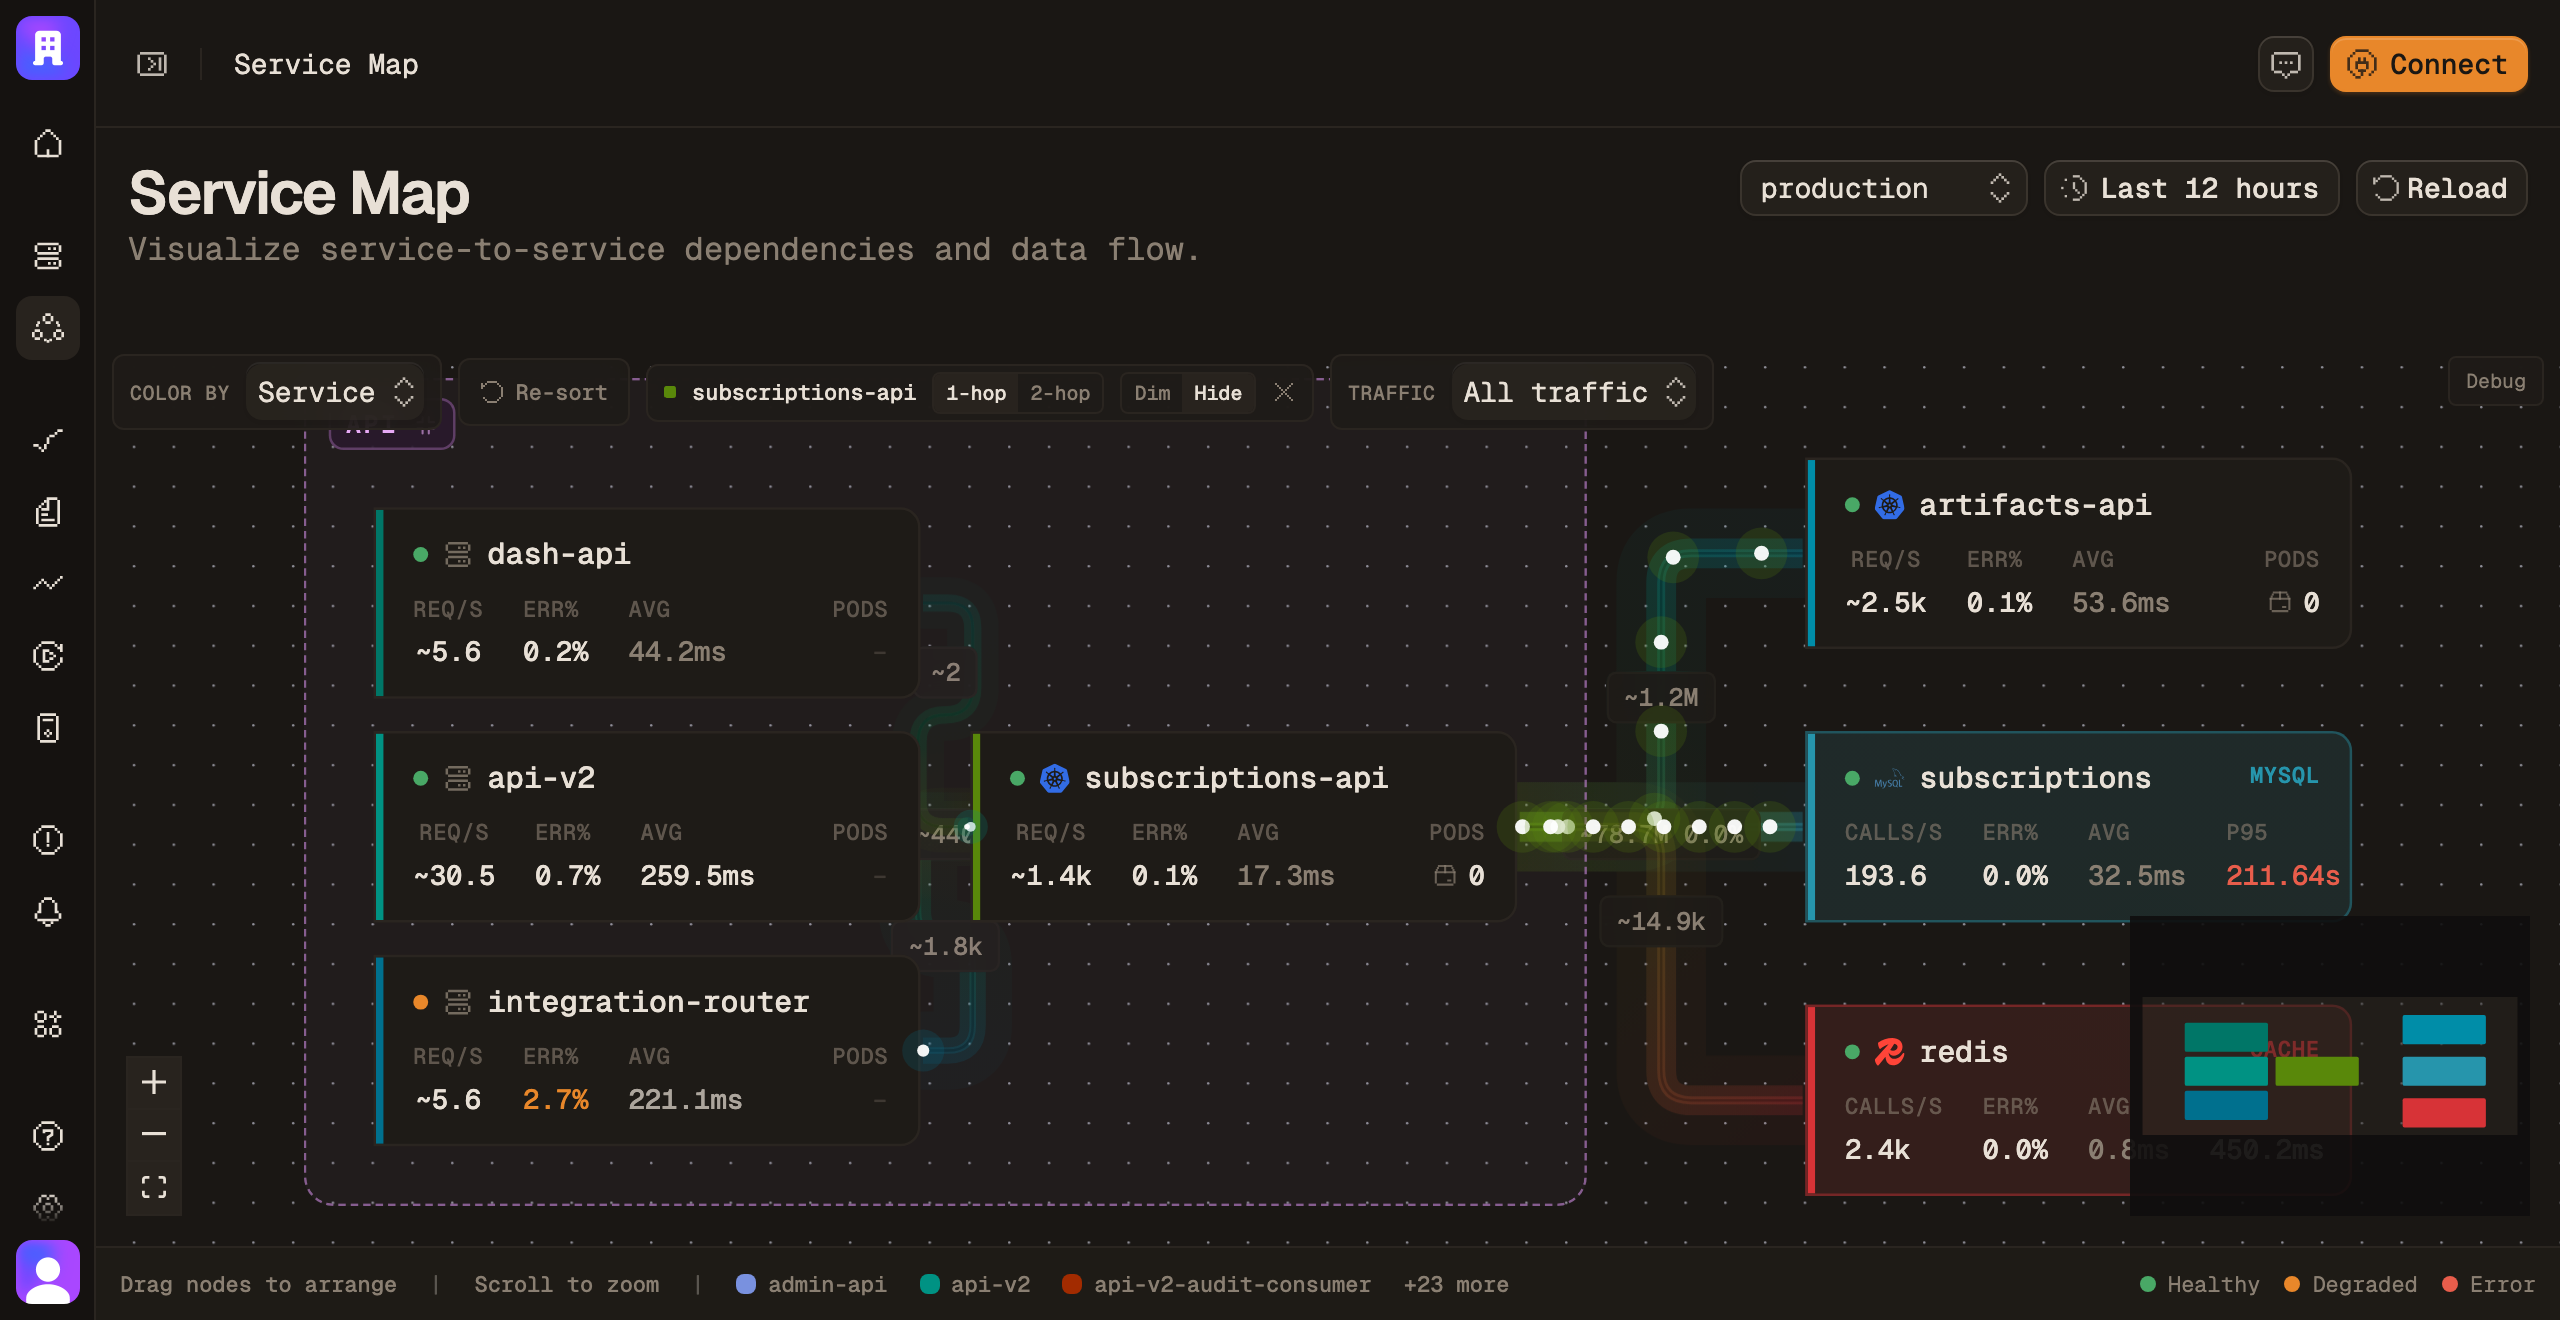
The map shows a slow edge
api-gateway is the service being paged about, but its own spans are fine. The degraded edge is two hops in: payment-svc to user-db, p95 up from 12 ms to 210 ms.
- trace T+1:10 · deploy payment-svc@1.4.2
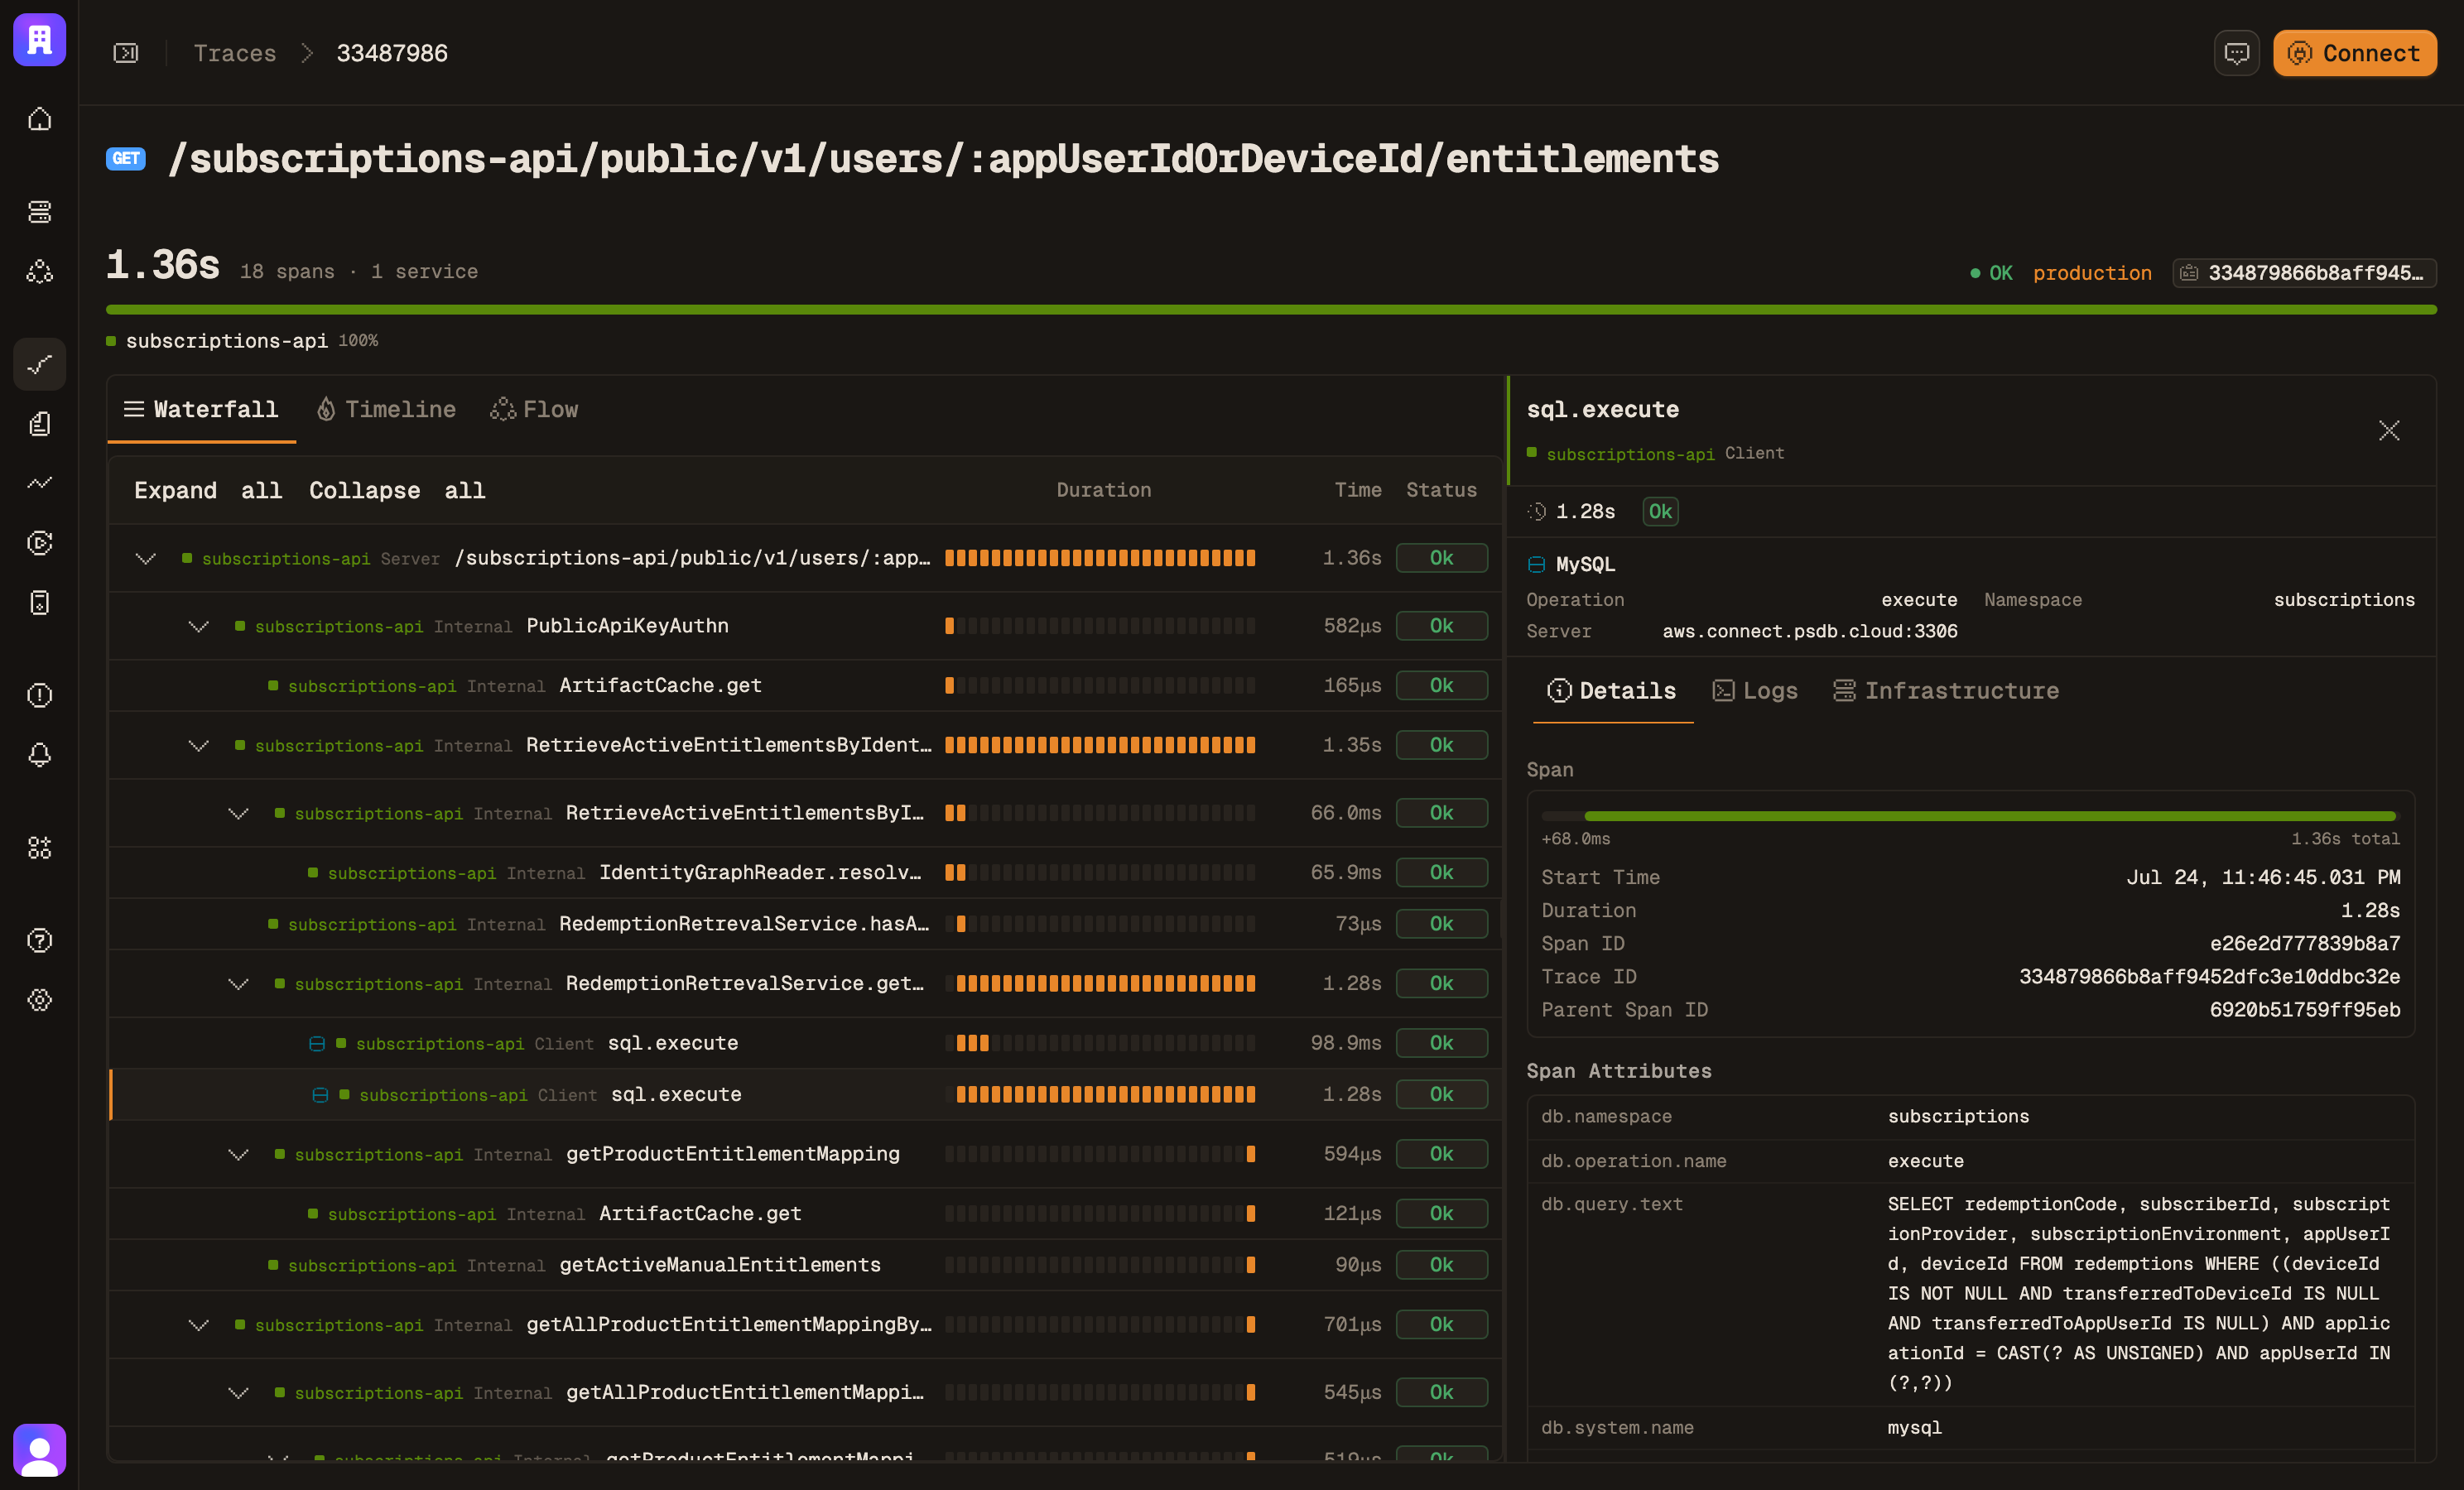
The trace shows the wait
Open a slow request and the db span is almost all of it. The query itself takes 4 ms, but the span takes 210 ms. The other 206 ms was spent waiting before the query ran.
- logs T+2:40 · deploy payment-svc@1.4.2
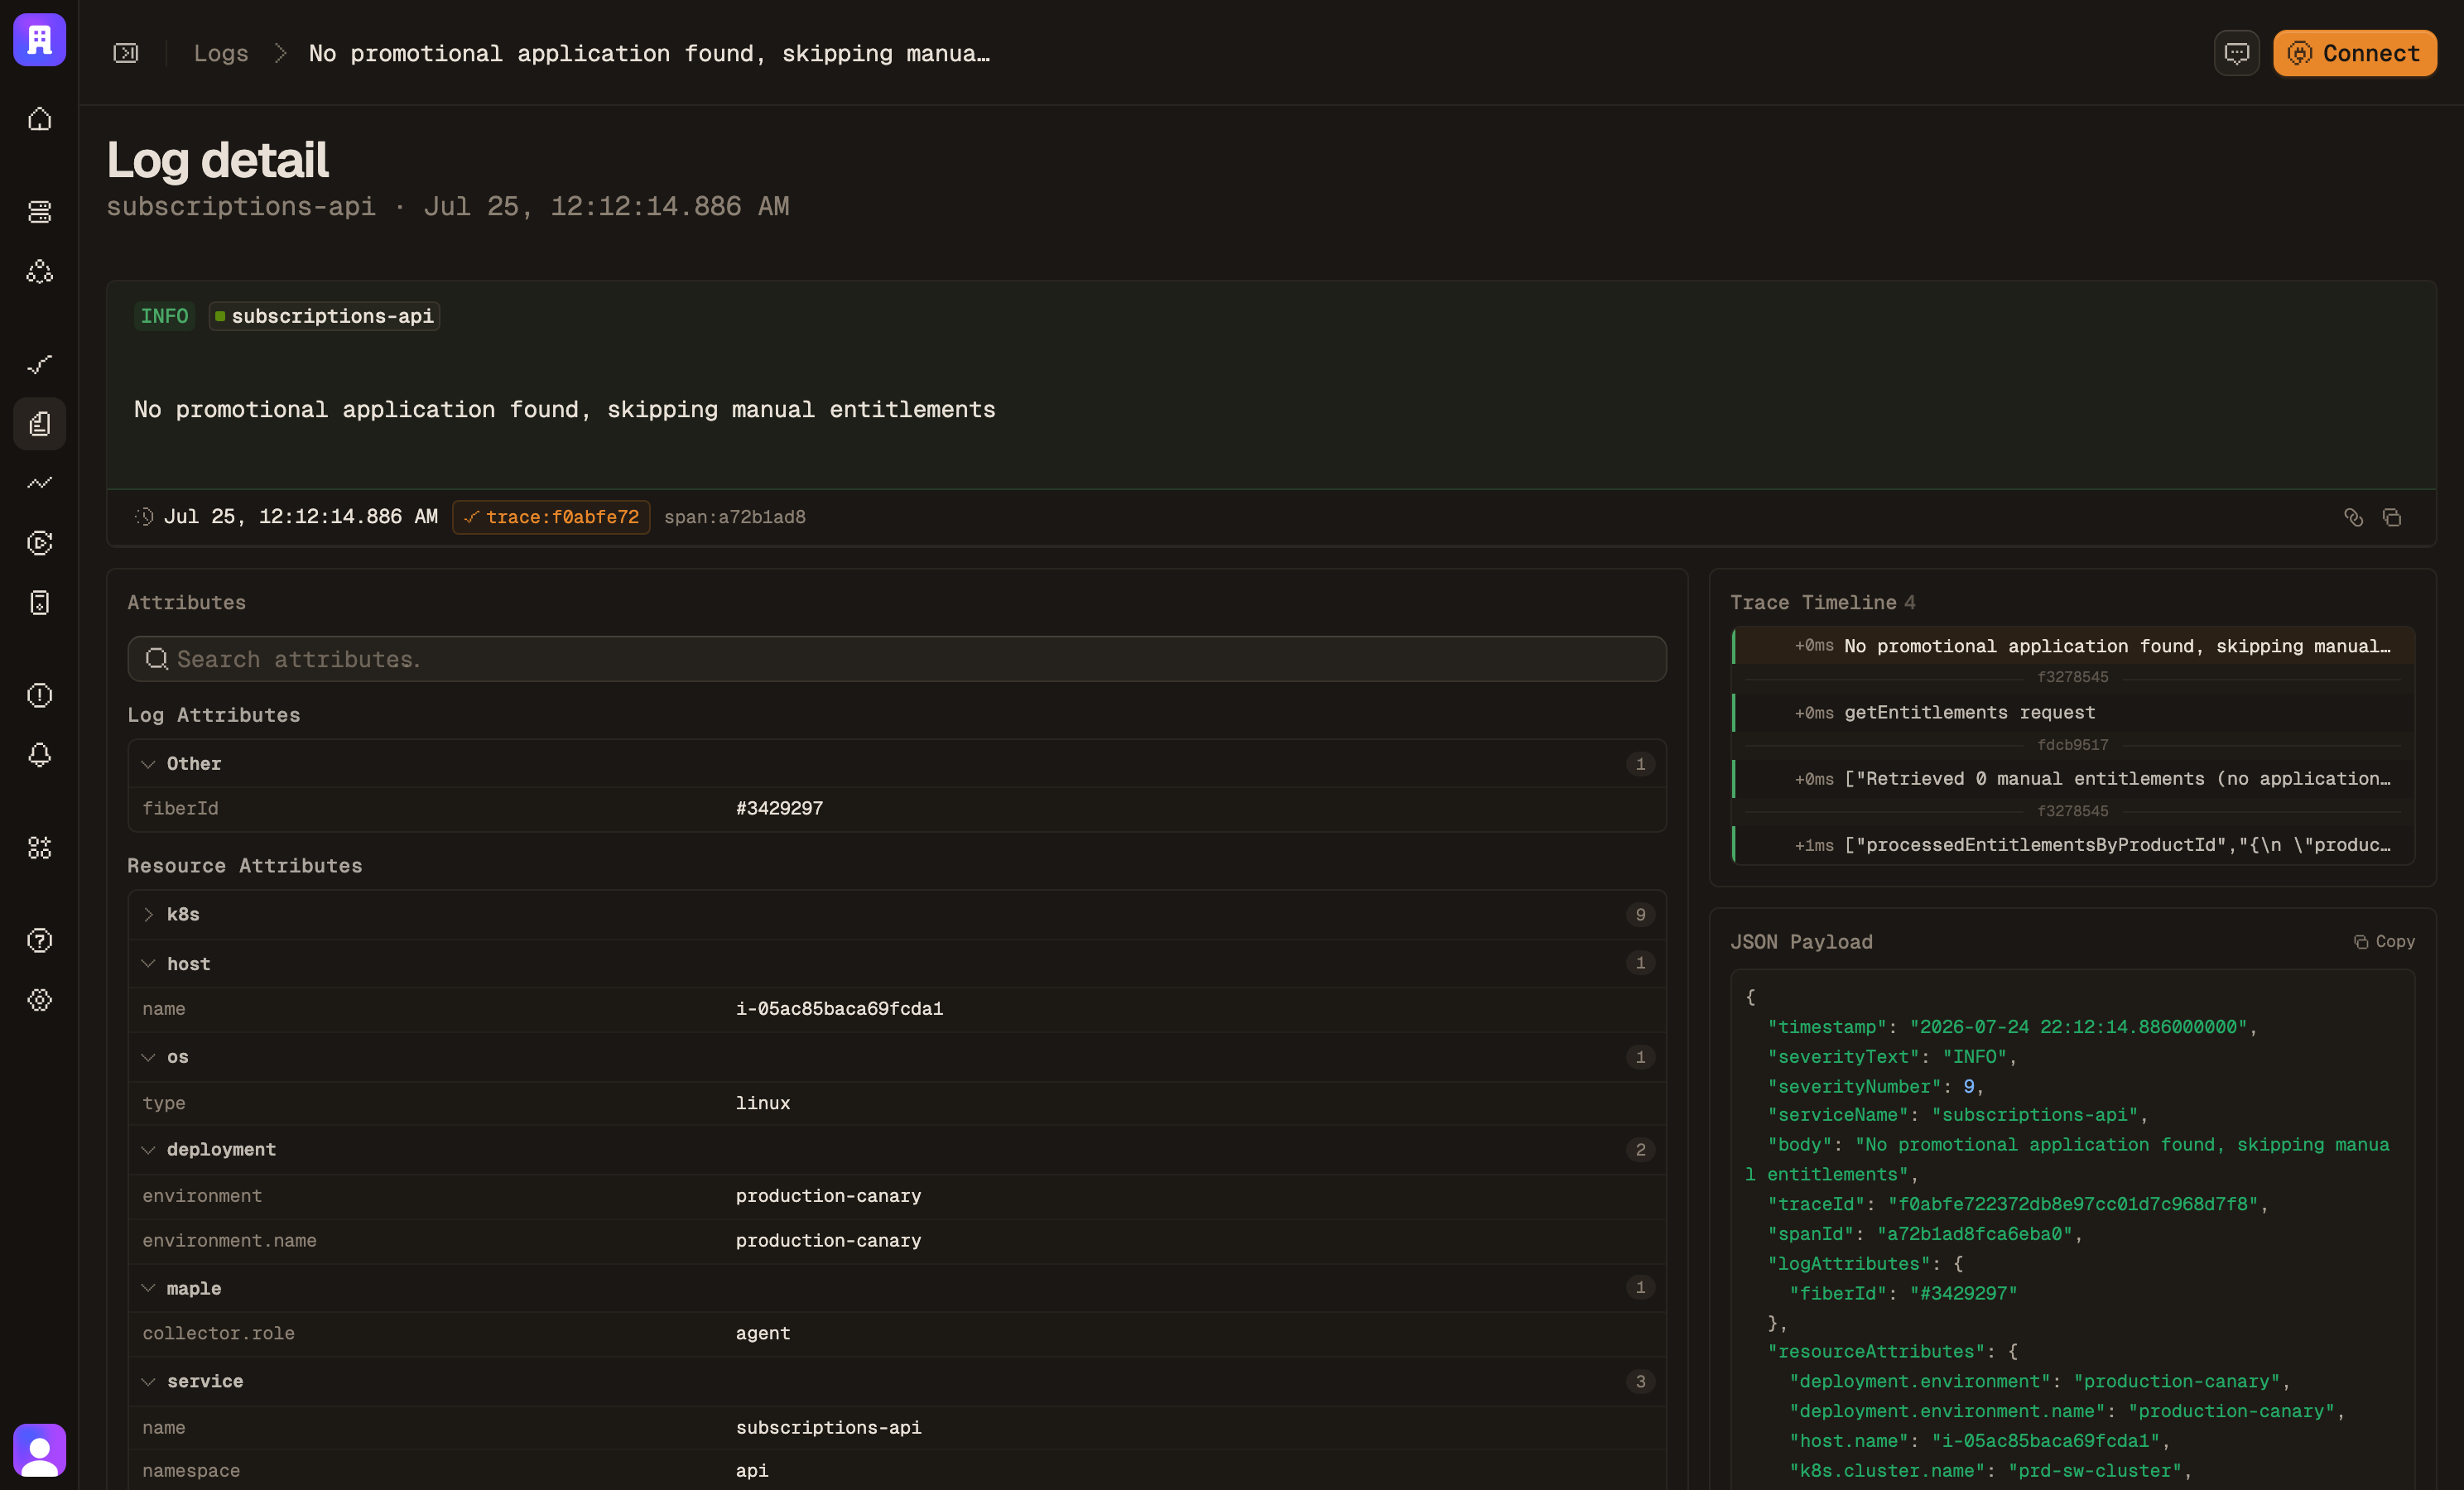
The logs name the release
Lines from that span read pool wait 206 ms, acquired after 3 attempts. Filter by service.version and they start at 1.4.2, which raised concurrency without raising the pool.